Category Archives: News

Zooniverse, GitHub and the future

In case you haven’t noticed I’ve had a pretty busy five years at the Zooniverse. With more than 25 projects launched in fields from astronomy to biodiversity and from climataology all the way to zoology, it’s been an incredible experience to work with so many new science teams hungry for answers to research questions that can only be answered by enlisting the help of a large number of volunteers. This model of citizen science, one where we boil down the often complex analysis task brought to us by a science team to the ‘simplest thing that will work’, build a rich user experience and then ask a bunch of people to help, seems to work pretty well.

For me, one of the best aspects of what I get to do is that I work in a domain that is an inherently open way of doing research. Having joined Zooniverse when we were still ‘just’ Galaxy Zoo, to see the range of projects we host broaden and to watch our community mature has been a remarkable experience. With our latest endeavour – the Galaxy Zoo Quench project – it’s clear that the line between the activites of the ‘science’ team and the ‘volunteers’ is becoming less defined by the day. Citizen-led science in the Zooniverse began with a group of people in the Galaxy Zoo Forum, ‘The Peas Corp’ when they discovered a new class of galaxy, and it continues today with volunteers discovering new types of worms, exotic exoplanets and even, through Quench, analysing and writing a new paper as a group. These of course are just examples I’ve taken from the Zooniverse and there are many more in other projects run by other people, but in each case the result is the same: by enagaing the public in a meaningful way Citizen Science is challenging the centuries old practices of academia and that has to be a good thing.

The opportunity to change the way science is done, whether it’s building software to increase efficiency or developing new collaboration models, is what brought me to the Zooniverse and now it’s what is leading me away. At the end of September this year I’m going to be hanging up my hat as Technical Lead of the Zooniverse and joining GitHub as their ‘science guy’.

As with all big decisions in life this wasn’t an easy one. I feel very fortunate to have had the opportunity to give technical direction to an incredible team of scientists, developers, educators and designers here at the Adler and the wider Zooniverse. But over the past couple of years I’ve also got to know a number of the GitHub folks and I’ve been hugely impressed by their focus on building the very best platform possible for online collaboration. Starting with the very simple idea that ‘it should be easier to work together than alone’ they’ve clearly nailed what it looks like to work on a problem with others in code. But software isn’t the only thing people are sharing on GitHub – legislators are publishing drafts of state law, technicians are documenting scientific laboratory protocols and with tools like the IPython Notebook researchers have defined formats and means of sharing entire research workflows.

The mantra of ‘collaborative versioned science’ has been rattling around my head now for a couple of years. I believe there’s an opportunity for GitHub to be the platform for capturing the process of scientific discovery and I want to help make that happen.

So what does this mean for the Zooniverse? Well, I’m leaving at a pretty good time as the Zooniverse has never been healthier – there’s a first-class web and education team of twelve people I’m going to be leaving behind at the Adler Planetarium in Chicago and we’ve just secured several large grants to expand our sister team at The University of Oxford to ten people (watch this space for job ads).

With all of these people and a number of major development projects in the pipeline we’re going to need a new Technical Lead. If this sounds fun, like you might be a good fit (and you’re able to work in the UK or US) then drop myself and Chris Lintott a line (we’re arfon@zooniverse.org and chris@zooniverse.org) – we’d love to talk. Our software is a mixture of Ruby, Rails and Javascript and we like using technologies like MongoDB, Redis, Amazon Web Services and Hadoop. We get to work on hard data science problems, build custom software for solving crowdsourcing at scale and work with some incredibly smart and creative collaborators.  Whoever takes over is going to have a lot of fun.

Arfon

PS If you’d like to know more about what work looks like as a Technical Lead of the Zooniverse then I’ve written recently about some of the problems we’ve addressed over the past few years herehere and here.

(Many) Zooniverse Papers Now Open Access

You don’t have to hang around the Zooniverse very long to find out that we’re rather proud of our growing list of publications. We think it’s essential that these papers are available to everyone which is why, for example, we’ve been posting versions of the astronomical papers on arXiv’s Astro-Ph. This is where I get papers I want to read, anyway, but there are advantages to occasionally being able to access the ‘real thing’ – the journal’s own version of the paper.

The doors to the Bodelian library in Oxford are labelled by subject. The one on the left here serves both astronomy and rhetoric. Credit : Jim Linwood

I’m delighted, therefore, to say that Oxford University Press, publishers of the journal we most frequently submit papers to have agreed to make all Zooniverse papers completely free to access. This applies to any Zooniverse paper in Monthly Notices of the Royal Astronomical Society (which is neither monthly nor contains notices of the Royal Astronomical Society), so whether you want to read about bulgeless galaxies, the Solar System’s dust, the supernovae we discovered, Planet Hunters results or Milky Way Project bubbles you can now do so from the journal itself.

How the Zooniverse Works: Keeping It Personal

This the the third post in a series about how, at a high level, the Zooniverse collection of citizen science projects work. In the first post I describe the core domain model description that we use – something that turns out to be a crucial part of faciliating conversation between scienctists and developers. In the second I covered about some of the core technologies that keep things running smoothly. In this and the next few posts I’m going to talk about parts of the Zooniverse that are subtle but important optimisations. Things such as how we pick which Subject to show to someone next, how we decide when a Subject is complete, and measuring the quality of a person’s Classifications.

Much of what I’m about to describe probably isn’t obvious to the casual observer but these are some of the pieces of the Zooniverse technical puzzle that as a team we’re most proud of and have taken many iterations over the past five years to get right. This post is about how we decide what to show to you next.

A Quick Refresher

At its most basic, a Zooniverse citizen science project is simply a website that shows you some data images, audio or plots, asks you to perform some kind of analysis on interpretation on it and collects back what you said. As I described in my previous post we’ve abstracted most of the data-part of that workflow into an API called Ouroboros which handles functionality such as login, serving up Subjects and collecting back user-generated Classifications.

Keeping it Fast

The ability for our infrastructure to scale quickly and predictably is a major technical requirement for us. We’ve been fortunate over the past few years to receive a fair bit of attention in the press which can result in tens or hundreds of thousands of people coming to our projects in a very short period of time. When you’re dealing with visitor numbers at that scale ideally you want everyone to have a pleasant experience.

Let’s think a little more about what absolutely has to happen when a person visits for example Galaxy Zoo.

  1. We need to show a login/signup form and send the information provided by the individual back to the server.
  2. Once registration/login is complete we need to serve back some personal information (such as a screen name).
  3. We need to pick some Subjects to show.

For many of the operations that happen in the Zooniverse, a record is written to a database somewhere. When trying to improve the performance of code that involves databases, a key strategy is to try and avoid querying these database as much as possible especially if the queries are complex and the databases are large as these are often the slowest parts of your application.

What count’s as ‘complex’ and ‘big’ in database terms varies based upon the types of records that you are storing, the choices you’ve made about how to index them and the resources you provide to the database server i.e. how much RAM/CPU you have available.

Keeping it personal

If there’s one place that complex queries are guaranteed to reside in a Zooniverse project codebase then it’s the part where we decide what to show to a particular person next. It’s complex, in need of optimisation and potentially slow for a number of reasons:

  1. When selecting a Subject we need to pick from one that a particular User hasn’t seen before.
  2. Often Subjects are in Groups (such as a collection of records in Notes from Nature) and so these queries have to happen within a particular scope.
  3. We often want to prioritise a certain subset of the Subjects.
  4. These queries happen a lot, at least n * the total number of Subjects (where n is the number of repeat classifications each Subject receives).
  5. The list of Subjects we’re selecting from is often large (many millions).

On first inspection, writing code to achieve the requirements above might not seem that hard but if you add in the requirement that we’d like to be able to select Subjects hundreds of times per second for many thousands of Users then it starts to get tricky.

A ‘poor man’s’ version of this might look something like this

def self.next_original_for_user(user)
  recents = joins(:classifications).where(:classifications => { :zooniverse_user_id => user.id }).select('subjects.id').all
  if recents.any?
    where(['id NOT IN (?)', recents]).first
  else
    first
  end
end

What we’re doing here is finding all the classifications for a given User and grabbing all of the Subject ids for them. Then we do a SQL select to grab the first record that doesn’t have an id matching one of the ones from existing classifications.

While this code is perfectly valid and would work OK for small-scale datasets there are a number of core issues with it:

  1. It’s pretty much guaranteed to get slower over time – as the number of classifications grows for a user retrieving the recent classifications is going to become a bigger and bigger query.
  2. It’s slow from the start – NOT IN queries are notoriously slow.
  3. It’s wasteful – every time we grab a new Subject for a User we essentially run the same query to grab the recent classification Subject ids.

These factors combined make for some serious potential performance issues if we want to execute code like this frequently, for large numbers of people and across large datasets all of which are requirements for the Zooniverse.

A better way

It turns out that there are technologies out there designed to help with this sort of scenario. When we select the new Subject for a user there’s no reason why this operation has to actually happen in the database that the Subjects are stored in, instead we can keep ‘proxy’ records stored in lists or sets. That means that if we have a big list of ids of things that are available to be classified and a list of ids of things that each user has seen so far then when we want to select a Subject for someone we just subtract those two things and then pick randomly from the difference and pluck that record from the database.

Screen Shot 2013-07-22 at 21.35.20

In the diagram above when Rob (in the middle) comes to one of our sites we subtract from the big list of Subjects that need classifying still (in blue) the list of things that he’s already seen (in green) and then pick randomly from that resulting set. Going by this diagram it looks like we must have to keep a list of available Subjects for each project together with a separate list of Subjects per project per user so that we can do this subtraction and that’s exactly the case. The database technology that we use to do this is called Redis and it’s designed for operations just like this.

The result

Maturing our codebase to a point where the queries described above are straightforward has been a lot of work, mostly by this guy. What does it look like to actually require this kind of behaviour in code? Just two lines:

class BatDetectiveSubject < Subject
  include SubjectSelector
  include SubjectSelector::Unique
end

This example is selecting ‘unique’ records for each user. We can also select unique grouped and prioritised unique records for projects like Planet Hunters. Regardless of the selection ‘flavour’ we’re using it’s simple for us to now to implement selection behaviour, using Redis to perform these selection operations means that everything is insanely quick, typically returning from Redis in ~30ms even for databases with many tens of thousands of Subjects to be classified.

Screen Shot 2013-07-22 at 22.14.00

Making the routinely hard stuff easier is a continual goal for the Zooniverse development team. That way we can focus maximum effort on the front-end experience and what’s different and hard about each new project we build.

Chasing Storms Online with the New Cyclone Center

Cyclone Center has recorded almost 250,000 classifications from volunteers around the world since its launch in September 2012. We’ve had lots of feedback on the project and have recently made significant changes that we think will make the experience of classifying storms more rewarding.

Patterns in storm imagery are best recognized by the human eye, so the scientists behind Cyclone Center are asking you to help look through 30 years of images of tropical storms. The end product will be a new global tropical cyclone dataset that could not be realistically obtained in any other fashion. We have already found that the pattern matching by our classifiers is doing better in many cases than a computer algorithm on the same images – this is very exciting!

The biggest change to the site is that we’re now targeting storms for classification. We’ve shifted to a system where the whole community will work on particular storms until they’re finished. This produces useful data very quickly – and means we can classify timely and scientifically useful storms as needed. These targeted storms will change frequently as you help us complete each one. You can check a box on the Cyclone Center home page that will mean you get alerted when new targeted storms appear: we hope to recruit a horde of enthusiastic online storm chasers this way.

Cyclone Centre Homepage

We’ve added much more inline classification guidance – gone are the days of clicking on question marks to get help.  For each step in the process, you will be shown information on how to best answer the question. We think this will give you more confidence in what you are doing and hopefully inspire you to do even more!

We’ve improved the tutorial and we’re providing more feedback as you go along – now instead of waiting for several images to see the “Storm Stats” page, you will immediately go there after your first image. We’ve also upgraded Cyclone Center Talk, which allows for better searching and highlights more of the interesting discussions going on between other citizen scientists.

All-in-all it’s a big change for an awesome project. Log in to Cyclone Center today and give the new version a try. Don’t forget to check the box to start getting alerted to new storms as they appear: this will be incredibly useful for the research behind the site, and means you can be the first to classify data on new storms.

[Visit http://www.cyclonecenter.org and see the blog at http://blog.cyclonecenter.org]

Zoo Tools: A New Way to Analyze, View and Share Data

Since the very first days of Galaxy Zoo, our projects have seen amazing contributions from volunteers who have gone beyond the main classification tasks. Many of these examples have led to scientific publications, including Hanny’s Voorwerp, the ‘green pea’ galaxies, and the circumbinary planet PH1b.

One common thread that runs through the many positive experiences we’ve had with the volunteers is the way in which they’ve interacted more deeply with the data. In Galaxy Zoo, much of this has been enabled by linking to the Sloan SkyServer website, where you can find huge amounts of additional information about galaxies on the site (redshift, spectra, magnitudes, etc). We’ve put in similar links on other projects now, linking to the Kepler database on Planet Hunters, or data on the location and water conditions in Seafloor Explorer.

The second part of this that we think is really important, however, is providing ways in which users can actually use and manipulate this data. Some users have been already been very resourceful in developing their own analysis tools for Zooniverse projects, or have done lots of offline work pulling data into Excel, IDL, Python, and lots of other programs (see examples here and here). We want to make using the data easier and available to more of our community, which has led to the development of Zoo Tools (http://tools.zooniverse.org). Zoo Tools is still undergoing some development, but we’d like to start by describing what it can do and what sort of data is available.

An Example

Zoo Tools works in an environment which we call the Dashboard – each Dashboard can be thought of as a separate project that you’re working on. You can create new Dashboards yourself, or work collaboratively with other people on the same Dashboard by sharing the URL.

Zoo Tools Main Page

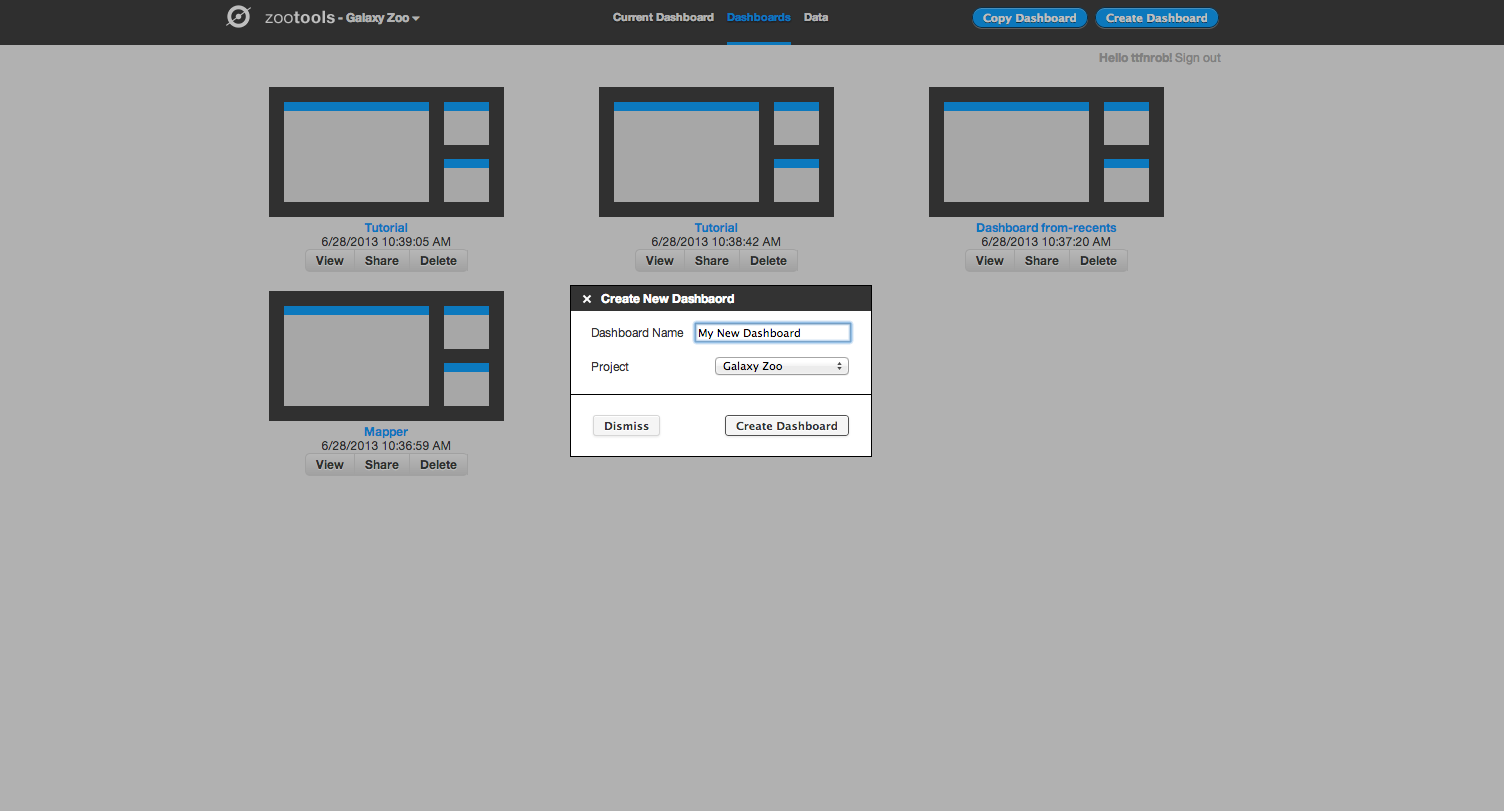
Create a New Dashboard

Within the Dashboard, there are two main functions: selecting/importing data, and then using tools to analyze the data.

The first step for working with the Dashboard is to select the data you’d like to analyze. At the top left of the screen, there’s a tab named “Data”. If you click on this, you’ll see the different databases that Zoo Tools can query. For Galaxy Zoo, for example, it can query the Zooniverse database itself (galaxies that are currently being classified by the project), or you can also analyze other galaxies from the SDSS via their Sky Server website.

Import Data from Zooniverse

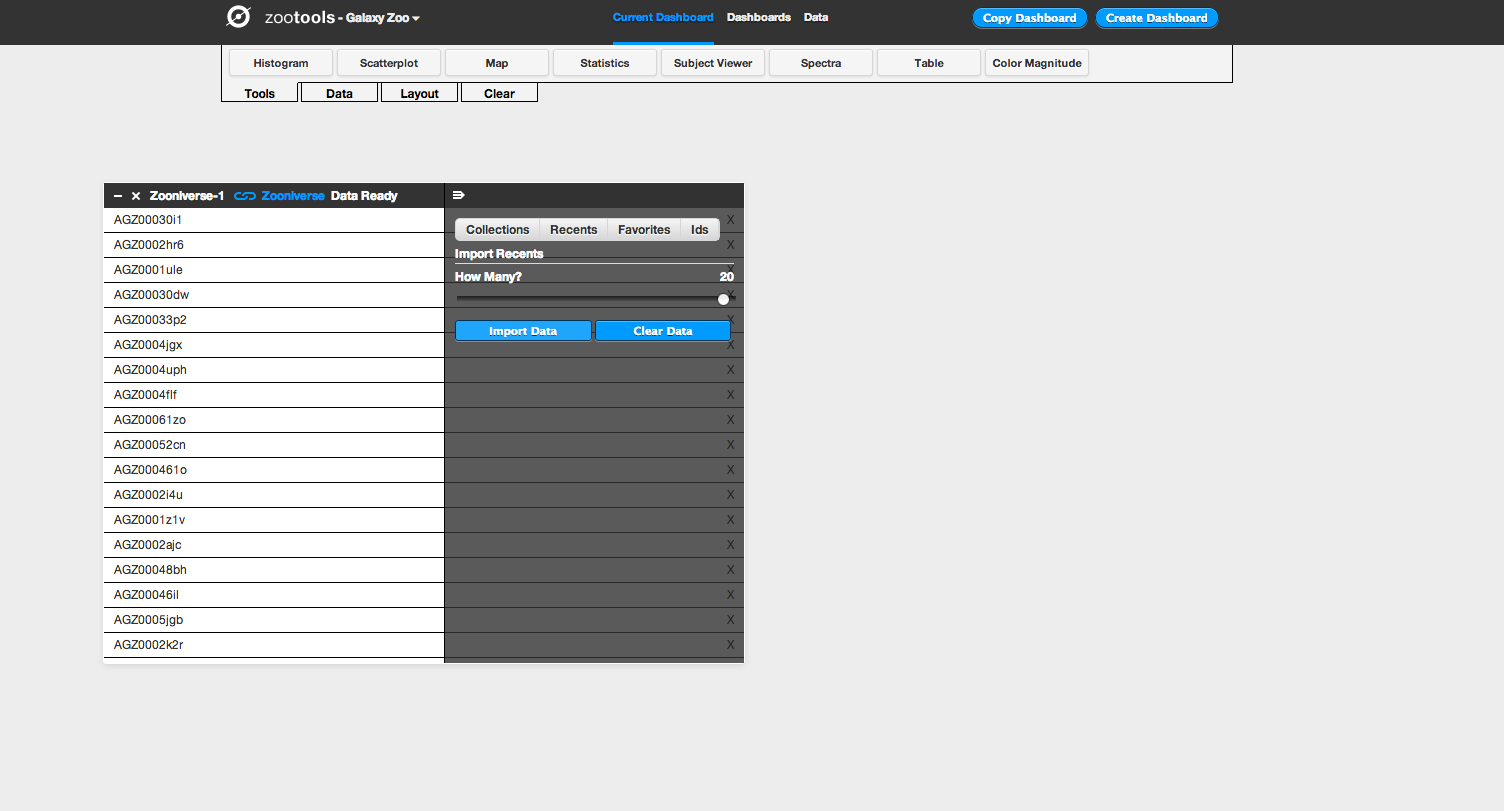
Clicking on the “Zooniverse” button, for example, you can select galaxies in one of four ways: a Collection (either your own or someone else’s), looking at your recently classified galaxies, galaxies that you’ve favorited, or specific galaxies via their Zooniverse IDs. Selecting any of these will import them as a dataset, which you can start to look at and analyze. In this example we’ll import 20 recent galaxies.

Import 20 Recents

After importing your dataset, you can use any of the tools in Dashboard (which you can select under “Tools” at the top of the page) on your data. After selecting a tool, you choose the dataset that you’d like to work with from a dropdown menu, and then you can begin using it. For example: if I want to look at the locations of my galaxies on the sky, I can select the “Map” tool. I then select the data source I’d like to plot (in this case, “Zooniverse–1”) and the tool plots the coordinates of each galaxy on a map of the sky. I can select different wavelength options for the background (visible light, infrared, radio, etc), and could potentially use this to analyze whether my galaxies are likely to have more stars nearby based on their position with respect to the Milky Way.

The other really useful part is that the tools can talk to each other, and can pass data back and forth. For example: you could import a collection of galaxies and look at their colour in a scatterplot. You could then select only certain galaxies in that tool, and then plot the positions of those galaxies on the map. This is what we do in the screenshots below:

This slideshow requires JavaScript.

Making Data Analysis Social

You can also share Dashboards with other people. From the Zoo Tools home page you can access your existing dashboards as well as delete them and share them with others. You can share on Twitter and Facebook or just grab the URL directly. For example, the Dashboard above can be found here – with a few more tools added as a demonstration.

Sharing a Dashboard

This means that once you have a Dashboard set up and ready to use, you can send it to somebody else to use too. Doing this will mean that they see the same tools in the same configuration, but on their own account. They can then either replicate or verify your work – or branch off and use what you were doing as a springboard for something new.

What ‘Tools’ Are There?

Currently, there are eight tools available for both regular Galaxy Zoo and the Galaxy Zoo Quench projects:

  • Histogram: makes bar charts of a single data parameter
  • Scatterplot: plot any two data parameters against each other
  • Map: plot the position of objects on the sky, overplotted on maps of the sky at different wavelengths (radio, visible, X-ray, etc.)
  • Statistics: compute some of the most common statistics on your data (eg, mean, minimum, maximum, etc).
  • Subject viewer: examine individual objects, including both the image and all the metadata associated with that object
  • Spectra: for galaxies in the SDSS with a spectrum, download and examine the spectrum.
  • Table: List the metadata for all objects in a dataset. You can also use this tool to create new columns from the data that exists – for example, take the difference between magnitudes to define the color of a galaxy.
  • Color-magnitude: look at how the color and magnitude of galaxies compare to the total population of Galaxy Zoo. A really nice way of visualizing and analyzing how unusual a particular galaxy might be.

We have one tool up and running for Space Warps called Space Warp Viewer. This lets users adjust the color and scale parameters of image to examine potential gravitational lenses in more detail.

Snapshot Serengeti Dashboard

Finally, Snapshot Serengeti has several of the same tools that Galaxy Zoo does, including Statistics, Subject Viewer, Table, and Histogram (aka Bar Graph). There’s also Image Gallery, where you can examine the still images from your datasets, and we’re working on an Image Player. There’s a few very cool and advanced tools we started developing last week – they’re not yet deployed, but we’re really excited to let you follow the activity over many seasons or by focusing on particular cameras. Stay tuned. You can see an example Serengeti Dashboard, showing the distribution of Cheetahs, here (it’s also shown in the screenshot above).

We hope that Zoo Tools will be an important part of all Zooniverse projects in the future, and we’re looking forward to you trying them out. More to come soon!

Galaxy Zoo Quench: A New Kind of Citizen Science

A new ‘mini’ project went live yesterday called Galaxy Zoo Quench. This project involves new images of 6,004 galaxies drawn from the original Galaxy Zoo. As usual, everyone is invited to come and classify these galaxies, but this project has a twist that makes it special! We hope to take citizen science to the next level by providing the opportunity to take part in the entire scientific process – everything from classifying galaxies to analyzing results to collaborating with astronomers to writing a scientific article!

Galaxy Zoo Quench

Galaxy Zoo Quench is examining a sample of galaxies that have recently and abruptly quenched their star formation. These galaxies are aptly named Post-Quenched Galaxies. They provide an ideal laboratory for studying galaxy evolution. So that’s exactly what we want to do: with the help of the Zooniverse community. We hope you’ll join us as we try out a new kind of citizen science project. Visit http://quench.galaxyzoo.org to learn more.

The entire process of classifying, analyzing, discussing, and writing the article will take place over an ~8-12 week period. After classifying the galaxies, Quench volunteers can use tools.zooniverse.org to plot the data and look for trends. We also have a special Quench Talk forum to discuss and identify key results to include in the paper – above you can see examples of some of the cool objects people have already found and discussed.

Have questions about the project? Leave a comment here or ask us on Twitter (@galaxyzoo) or on the Galaxy Zoo Facebook page. In case you’re worried: the regular Galaxy Zoo will continue as normal.

Now go visit http://quench.galaxyzoo.org and start classifying!

Welcome to the Worm Watch Lab

Today we launch a new Zooniverse project in association with the Medical Research Council (MRC) and the Medical Research Foundation: Worm Watch Lab.

We need the public’s help in observing the behaviour of tiny nematode worms. When you classify on wormwatchlab.org you’re shown a video of a worm wriggling around. The aim of the game is to watch and wait for the worm to lay eggs, and to hit the ‘z’ key when they do. It’s very simple and strangely addictive. By watching these worms lay eggs, you’re helping to collect valuable data about genetics that will assist medical research.

Worm Watch Lab

The MRC have built tracking microscopes to record these videos of crawling worms. A USB microscope is mounted on a motorised stage connected to a computer. When the worm moves, the computer analyses the changing image and commands the stage to move to re-centre the worm in the field of view. Because the trackers work without supervision, they can run eight of them in parallel to collect a lot of video! It’s these movies that we need the public to help classify.

By watching movies of the nematode worms, we can understand how the brain works and how genes affect behaviour. The idea is that if a gene is involved in a visible behaviour, then mutations that break that gene might lead to detectable behavioural changes. The type of change gives us a hint about what the affected gene might be doing. Although it is small and has far fewer cells than we do, the worm used in these studies (called C. elegans) has almost as many genes as we do! We share a common ancestor with these worms, so many of their genes are closely related to human genes. This presents us with the opportunity to study the function of genes that are important for human brain function in an animal that is easier to handle, great for microscopy and genetics, and has a generation time of only a few days. It’s all quite amazing!

To get started visit www.wormwatchlab.org and follow the tutorial. You can also find Worm Watch Lab on Facebook and on Twitter.

52 Years of Human Effort

At ZooCon last week I spoke about the scale of human attention that the Zooniverse receives. One of my favourite stats in this realm (from Clay Shirky’s book ‘Cognitive Surplus’) is that in the USA, adults cumulatively spend about 200 billion hours watching TV every year. By contrast it took 100 million hours of combined effort for Wikipedia to reach its status as the world’s encyclopaedia.

In the previous year people collectively spent just shy of half a million hours working on Zooniverse projects. Better put, the community invested about 52 years worth of effort[1]. That’s to say that if an individual sat down and did nothing but classify on Zooniverse sites for 52 years they’d only just have done the same amount of work as our community did between June 2012 and June 2013. The number is always rising too. Citizen science is amazing!

Another way of thinking about it is to convert this time into Full Time Equivalents (FTEs). One person working 40 hours per week, for 50 weeks a year works for 2000 hours a year – that’s 1 FTE. So our 460,000 hours of Zooniverse effort are equivalent to 230 FTEs. It’s as if we had a building with 230 people in who only came in every day to click on Zooniverse projects.

Zooniverse Effort Distribution to June 2013

This amazing investment by the community is not broken down evenly of course, as the above ‘snail’ chart shows. In fact Planet Hunters alone would occupy 62 of the people in our fictional building: the project took up 27% of the effort in the last year. Galaxy Zoo took 17%, which means it had almost 9 years of your effort all to itself. Planet Four had a meteoric launch on the BBC’s Stargazing Live less than six months ago and since that time it has gobbled up just over 5 years of human attention – 10% of the whole for the past year.

What’s wonderful is that our 230 metaphorical workers, and the 52 years they represent, are not confined to one building or one crazed click-worker. Our community is made of hundreds of thousands of individuals across the world – 850,000 of whom have signed up through zooniverse.org. Some of them have contributed a single classification, others have given our researchers far, far more of their time and attention. Through clicking on our sites, discussing ideas on Talk, or just spreading the word: Zooniverse volunteers are making a significant contribution to research in areas from astronomy to zoology.

Congratulations to everyone who’s taken part and let’s hope this number increases again by next year!

[1] In my ZooCon talk I incorrectly gave the figure of 35 years. This was wrong for two reasons; firstly, I had neglected Andromeda Project, Planet Four and Snapshot Serengeti for technical reasons. Secondly I had calculated the numbers incorrectly, in my rush to get my slides ready, and I underestimated them all by about 20%.

Anyone Fancy an Asteroid?

This could be the Asteroid Zoo logo
This might be the Asteroid Zoo logo

Anyone interested in astronomy on the web will be aware of the fabulous success of Planetary Resources’ fundraising effort to build and launch the ARKYD space telescope. They’ve already raised more than a million dollars – helped in part by a cunning plan to let you take a picture of yourself in space – but they’re not stopping there. With three days to go, we’re delighted to announce that they’re going to try and help us help Zooniverse volunteers hunt for potentially hazardous asteroids.

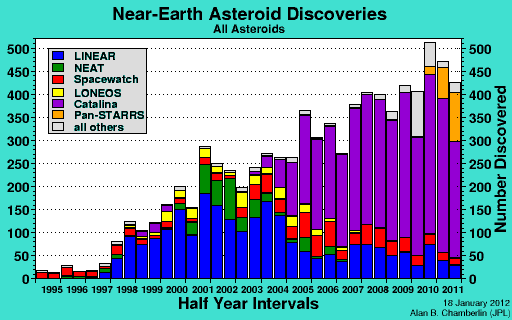
The latest stretch goal is to support the development by the Zooniverse of a citizen science asteroid hunt. If the new target is hit, we’ll build a system that uses more than 3 million images, taken data from the Catalina Sky Survey – the survey responsible for nearly half of the near Earth asteroid discoveries in the last fifteen years. We know there are asteroids out that are waiting to be discovered, and we’re willing to bet that the existing routines used to scan through the survey data didn’t find them all.

Recent discoveries of near-Earth objects; Catalina's the big purple part.
Recent discoveries of near-Earth objects; Catalina’s the big purple part.

Anyone who’s followed the Zooniverse over the last few years knows that we believe in doing projects that make authentic contributions to science, and so I’m especially pleased that the project with Planetary Resources is also focused on improving machine learning solutions to asteroid hunting. Rather like our supernova project, an ideal outcome would be to use the classifications provided by volunteers to improve automated searching and suggest new methods by which machines might take up the strain. In the meantime, though, there are new (small) worlds to find – with your help, we’ll be launching the search for them soon.

I’ve put my money where my mouth is already, and if you can afford it then I hope you’ll follow the link and donate so we can all go asteroid hunting. You can also watch their Kickstarter video to see what they’re trying to do.

PRI-KS-Banner-428x60

How the Zooniverse Works: Tools and Technologies

In my last post I described at length the domain model that we use to describe conceptually what the Zooniverse does. That wouldn’t mean much without an implementation of that model and so in this post I’m going to describe some of the tools and technologies that we use to actually run our citizen science projects.

The lifecycle of a Zooniverse project

Let’s think a little more about what happens when you visit a project such as Snapshot Serengeti. Ignoring all of the to-and-fro that your web browser does to work out where the domain name ‘snapshotserengeti.org’ points to, once it’s figured this and a few other details out you basically get sent a website that your browser renders for you. For the website to function as a Zooniverse project a few things are essential:

  1. You need to be able to view images (or listen to audio or watch a video) that we and the science team need your help analysing.
  2. You need to be able to log in with your Zooniverse account.
  3. We need to capture back what you said when doing the citizen science analysis task.
  4. Save out favourite images to your profile.
  5. View recent images you’ve seen in your profile.
  6. Discuss these images with the community.

It turns out that pretty much all of the functionality mentioned above is for us delivered by an application we call Ouroboros as an API layer and a website (such as Snapshot Serengeti) talking to it.

Screen Shot 2013-06-26 at 8.20.51 AM

Ouroboros – or ‘why the simplest API that works is probably all you need’.

So what is Ouroboros? It provides an API (REST/JSON) that allows you to build a Zooniverse project that has all of the core components (1-6) listed above. Technology-wise it’s a custom Ruby on Rails application (Rails 3.2) that uses MongoDB to store data and Redis as a query cache all running on Amazon Web Services. It’s probably utterly useless to anyone but us but for our needs it’s just about perfect.

Screen Shot 2013-06-26 at 8.01.30 AM

At the Zooniverse we’re optimised for a few different things. In no particular order of priority they are:

  1. Volume – we want to be able to build lots of projects.
  2. Science – we want it to be easy to do science with the efforts of our community.
  3. Scale/performance – we want to be able to have millions of people come to our proejcts and them to stay up.
  4. Availability – we’d prefer our websites to be ‘up’ and not ‘down’.
  5. Cost – we want to keep costs at a manageable level.

Pretty much all of these requirements point to having a shared API (Ouroboros) that serves a large number of projects (I’ll argue #4 in the pub with anyone who really wants to push me on it).

Running a core API that serves many projects makes you take the maintenance and health of that application pretty seriously. Should Ouroboros throw a wobbly then we’d currently take out about 10 Zooniverse projects at once and this is only set to increase. This means we’ve thought a lot about how to scale the application for times when we’re busy and we also spend significant amounts of time monitoring the application performance and tuning code where necessary. I mentioned that cost is a factor – running a central API means that when the Zooniverse is quiet and there aren’t many people about we can scale back the number of servers we’re running (automagically on Amazon Web Services) to a minimal level.

We’ve not always built our projects this way. The original Galaxy Zoo (2007) was an ASP/web forms application, projects between Galaxy Zoo 2 and SETI Live were all separate web applications, many of them built using an application called The Juggernaut. Building standalone applications every time not only made it difficult to maintain our projects but we also found ourselves writing very similar (but subtly different) code many times between projects, code for things like choosing which Subject to show next.

Ouroboros is an evolution of our thinking about how to build projects, what’s important and generalisable and what isn’t. At it’s most basic it’s a really fast Subject allocator and Classification collector. Our realisation over the last few years was that the vast majority of what’s different about each project is the user experience and classification interface and this has nothing to do with the API.

Subjects out, Classifications back in.

The actual projects

The point of having a central API is that when we want to build a new project we’re already working with a very familiar toolset – the way we log people in, do signup forms, ask for a Subject, send back Classifications – all of this is completely standard. In fact if you’re building in JavaScript (which we almost always are these days) then there’s a client library called ‘Zooniverse’ (meta I know) available here on GitHub.

Having a standard API and client library for talking to it meant that we built the Zooniverse project Planet Four in less than 1 week! That’s not to say it’s trivial to build projects, it’s definitely not, but it is getting easier. And having this standardised way of communicating with the core Zooniverse means that the bulk of the effort when building Planet Four was exactly where it should be – the fan drawing tools – the bit that’s different from any of our other projects.

Screen Shot 2013-06-26 at 8.19.22 AM

So how do we actually build our projects these days? We build our projects as JavaScript web applications using JavaScript web frameworks such as Spine JS, Backbone or something completely custom. The point being, that all of the logic for how the interface should behave is baked into the JavaScript application – Ouroboros doesn’t try and help with any of this stuff.

Currently the majority of our projects are hosted using the Amazon S3 static website hosting service. The benefits of this are numerous but key ones for us are:

  1. There’s no webserver serving the site content, that is http://www.galaxyzoo.org resolves to an S3 bucket. When you access the Galaxy Zoo site S3 does all of the hard work and we just pay for the bandwidth from S3 to your computer.
  2. Deploying is easy. When we want to put out a new version of any of our sites we just upload new timestamped versions of the files and your browser starts using them instead.
  3. It’s S3 – Amazon S3 is a quite remarkable service –  a significant fraction of the web is using it. Currently hosting more than 2 trillion (yes that’s 12 zeroes) objects and regularly serving more than 1 million requests for data per second the S3 service is built to scale and we get to use it (and so can you).

Amazon S3 is a static webhost (i.e. you can’t have any server-side code running) so how do we make a static website into a Zooniverse project you can log in to when we can’t access database records? The main site functions just fine – these JavaScript applications (such as the current Galaxy Zoo or any recent Zooniverse project) implement what is different about the project’s interface. We then use a small invisible iFrame on each website that actually points to api.zooniverse.org which is Ouroboros. When you use a login form we actually set a cookie on this domain and then send all of our requests back to the API through this iFrame. This approach is a little unusual and with browsers tightening up the restrictions on third-party cookies if looks like we might need to swap it out for a different approach but for now it’s working well.

Summing up

If you’re like me then when you read something you read the opening, look at the pictures and then skip to the conclusions. I’ll summarise here just incase you’re doing that too:

In the Zooniverse there’s a clear separation between the API (Ouroboros) and the citizen science projects that the community interact with. Ouroboros is a custom-built, highly scalable application built in Ruby on Rails, that runs on Amazon Web Services and uses MongoDB, Redis and a few other fancy technologies to do its thing.

The actual citizen science projects that people interact with are these days all pure JavaScript applications that are hosted on Amazon S3 and they’re pretty much all open source. They’re generally still bespoke applications each time but share common code for talking to Ouroboros.

What I didn’t talk about in this post are the hardest bits we’ve solved in Ouroboros – namely all of the logic about how to make finding Subjects for people quickly and other ‘smart stuff’. That’s coming up next.