I was slightly surprised to see my twitter feed this morning filling up with comments about how the term ‘citizen’ appears in writing about science, and about public engagement with science. This seems to be coming from Roland Jackson’s post in response to the publication of a report called ‘What publics? When?’ from Sciencewise, an organisation that gives advice on science policy to government. Roland’s point is that perhaps the reason we get ourselves in a tangle when talking about public engagement is the word ‘public’, thinking that ‘citizen’ does a better job of breaking down the divide between ‘us’ doing the engagement and the ‘public’ being engaged. (There’s another engaging comparison on Nottingham’s ‘Making Science Public’ blog.)
In such contexts, I reckon ‘citizen’ comes up most often in ‘citizen science’, and I thought it might be interesting to say something about our use of the term. It’s how we describe our projects in papers, and we chose it mostly because we didn’t like the term ‘crowdsourcing’, which never seem adequate for projects which very quickly demonstrated that they could grow way beyond simple requests for a community to complete a task. We quickly realised we wanted people to make discoveries, to follow them up themselves and to chase down their own research questions and crowdsourcing just doesn’t describe that. I also liked the fact that anyone – professional or amateur, project designer or participant – could be a citizen scientist.
We clearly weren’t that confident, though. Although the core collaboration that builds and runs the Zooniverse is the Citizen Science Alliance, we’ve mostly reserved that term for grant applications rather than using in the real word. (Let along the problems of being a citizen science group which produces humanities projects either deliberately or accidentally.) This reticence isn’t misplaced; it reflects my firm belief that noone in the history of the world has ever set down at a computer, opened their web browser and thought ‘I’m a citizen scientist. Let’s do some citizen science’. Zooniverse participants are fans of one or more of our projects, and they tend to have stumbled in and then found a comfortable environment where they can do exciting things, rather than started off by looking for a science project. (This is also, I think, reflected in the lack of traffic we get from citizen science portals like SciStarter.)
‘Citizen’ science, from this perspective isn’t any more inclusive than talking about ‘public engagement’. The most common alternative (‘PPSR’ or Public Participation in Scientific Research) doesn’t help either. If names are important, we need a new one for this thing that we’re doing, but as the person who has been most consistently wrong about naming Zooniverse projects (I voted against Galaxy Zoo, for starters!) I’m the last person to ask. Maybe we should crowdsource a solution….
Chris
PS I’m reminded of this slide deck from Arfon which proposes CBSR (Community Based Scientific Research) and PPFCSM (Public Participation as a Fundamental Component of the Scientific Method), although I think he’s kidding on the last one.
Hello for the Martin Wood Lecture Theatre in Oxford’s Department of Physics which is playing host to a crowd of Zooniverse volunteers and project members for ZooCon13. We’re recording the talks for later broadcast, but as a sneak preview I thought I’d liveblog the event.
Talk 1 – SpaceWarps
We’re kicking off with Aprajita Verma from Oxford and from Space Warps, the newest Zooniverse astronomy project. As is traditional when talking about gravitational lensing – the bending of light by matter, she’s using Phil Marshall’s Galaxy in a Wine Glass video.
SpaceWarps is much needed – LSST, the next generation of survey telescope, will produce something like 10000 galaxy scale lenses. It’s designed to map a very wide area of sky, which is perfect for finding rare things like lenses – and this will produce a lot of work as traditional lens hunting is very labour intensive. Not only do they need to be found, but they then need to be modeled.
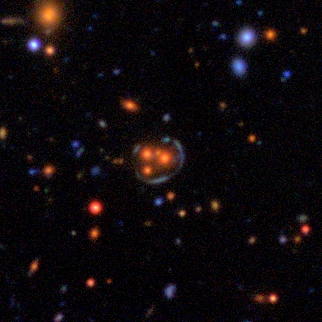
There are three lenses in this image – one real, and two simulated. Spotting the difference is hard…
Luckily – we have effort! 2 million 6 million classifications have been recorded already from over 8000 people. Particularly pleasing for me is that 40% of those people are discussing things on Talk – this is essential as lenses are complicated things and the interesting ones are going to be found through discussion. The team are doing dynamic assessment of the results, retiring images that no longer need classification – I especially liked their division of classifiers into ‘Optimists’ – who get lenses right but also get excited about lots of things that aren’t lenses – ‘Pessimists’ – who correctly dismiss non-lenses but get rid of lenses too – the ‘Astute’, who get everything right and the ‘Obtuse’, those who get everything wrong. Luckily, we have lots of astute classifiers and almost none who are obtuse, as evidenced by a sneak preview of the first few discoveries (more on those next week).
Talk 2 – Cosmic Evolution from Galaxy Zoo
Next up is Karen Masters of Portsmouth and Galaxy Zoo, talking about science results from the Zooniverse’s oldest project. It’s already clear there is lots of ground to cover in this conference and Karen’s bounding through a brief history of observational astronomy, noting the conceptual leap required to go from thinking about the Milky Way, our galaxy, and an expanding Universe filled with billions of the blighters. Karen just showed a cool movie showing the parts of the sky that have been mapped by the Sloan Digital Sky Survey, which provided images for the early incarnations of Galaxy Zoo.
A Galaxy in need of classifications.
In going through the history of Galaxy Zoo, Karen reminds me that the original BBC news story on Galaxy Zoo claims that we hope that 30,000 people will eventually take part. We smashed that on day one if I remember correctly. (There’s also a factual error in that news story – if anyone tells me what it is via Twitter (@chrislintott) or in person they can have a pint). While I relieve ancient history, Karen’s talking about her work on red spirals: most spirals are blue, but Galaxy Zoo helped us find lots of red ones and Karen says that the Milky Way may even be on its way to becoming one. The work on the red spirals was part of a serious shift in how we think about galaxy formation – a few years back that story was all about mergers but now it’s thought that lots of galaxies form and evolve (including fading from being a blue spiral to a red spiral) in slower, less spectacular ways.
Of course, one of the advantages of citizen science that Galaxy Zoo demonstrated was the ability of classifiers to discover the weird and wonderful. Recent examples include the bulgeless galaxies – spirals which are guaranteed not to have had a merger within the last few billion years – and a set of galaxies (mostly red spirals!) with massive bars at their centre. In even better news, we have time on the Very Large Array (I REPEAT – WE HAVE TIME ON THE VERY LARGE ARRAY!) to follow up on these things.
WE GOT TIME ON THE VERY LARGE ARRAY (this is a picture of some of it)
I’m really quite excited about the VLA. I’ve always wanted to use it.
Talk 3 – New Uses for Old Weather
We’re taking a break from astronomy with Philip Brohan from the Old Weather project – he’s explaining that scientists need historical observations to constrain their models of how the climate behaves. Lacking the ability to stick a weather satellite in the Tardis and head back in time, we need to scrabble around for old records, an idea that dates back to Beaufort of wind scale fame.
Philip in the gloaming, beneath an Old Weather slide.
This is great, but the supercomputers can’t read the 73 million logbook pages we’d like to sort through – hence the need for volunteers. So far more than a million logbook pages have been processed by the project – a small fraction of the total needed but a very useful quantity! Most of these volunteers are attracted by the historical information that the logs fortuitously contain – Philip is currently beneath a slide showing a log book containing both the information that the ship’s company are fitted with seal-skin boots, and that 23 dogs are received on board. (Why? Surely not for food…).
It’s all got a bit gruesome now – six dead bodies are being placed in alcohol. Luckily we’re swiftly on to HMS Tarantula, where their anemometer is infested with ants. The current set of logbooks have more famous events; in particular, the logbooks of the Jeannette show the discovery of the Arctic island now named after it (upon which nothing but ice sheets grow). The fact that we have these logbooks at all is a miracle; the ship was crushed by the ice and the crew (most of whom perished) chose to carry the scientific records with them as they struggled to safety.
Images from and about the Jeanette, including in the bottom left an artist’s impression of the chest of logbooks being saved.
As well as the climate and the history, Phil says, the third important aspect of Old Weather is the people. The project’s made particularly good use of the forum, which has steered the project in new directions and provided a home for discussion of things we never thought to look for, as well as art and verse. The latter was particularly inspired by the tragic loss of the chocolate aboard the HMS Manuta. Before rolling the credits listing his more than 17,000 collaborators, Philip ended these tales by noting that to make a serious dent on the archives we need to speed up by a factor of ten, a challenge the Zooniverse is happy to accept.
Talk 4 – The Future of Galaxy Zoo
Back to the Universe now, and Oxford’s Brooke Simmons is able to start her talk on what’s coming up for Galaxy Zoo by reminding the crowd that the data release paper for the second version of Galaxy Zoo is now with the referee. At about 30 pages, it’s as short as it could possibly be, showing the amount of effort that goes into dealing with classifications received via a large citizen science project.
Brooke’s now explaining the need – with Galaxy Zoo trying to reach back to a time not that long after the Big Bang – for us to use all sorts of tests to understand how our classifications work. Showing images of the same galaxies shifted to higher and higher redshifts (further and further away) it’s clear that classifications will change just because it’s harder to see what’s going on when galaxies get further away. We’re also playing with supercomputer simulations of the evolution of galaxies which shows how things change over time.
It’s not all about simulations, though – we’re thinking about moving beyond the optical range of the spectrum and looking at galaxies in the ultraviolet and infrared. The former, from a satellite called GALEX, shows only the youngest starts, the latter, from a survey called UKIDSS which covers about a third of the Sloan area, the dust and older stars. Also on the agenda are more advanced tools, like those which power the Galaxy Zoo Navigator which allows primarily school groups to look at the statistics of their classifications.
Correction I wasn’t listening properly to Aprajita; Spacewarps got 2 million classifications in the first week, and at the time of ZooCon was over 6 million. I’ve corrected the post. 1st July 2013.
Yesterday, five Zooniverse projects were featured in The Biologist’s 10 Great Citizen Science Projects – several of them were ideas proposed by researchers we had never met before they came to us and said ‘hey, I have a cool idea for a project‘. We’ve also recently seen articles about how the Zooniverse might be able to help in a crisis and how we provide an excellent avenue for proactive procrastination. Citizen science projects are wide and varied and lots of researchers have great ideas.
So this is a good time to remind everyone that we want to hear from researchers with ideas for Zooniverse projects. If that’s you: propose a project! We have funding from the Alfred P. Sloan Foundation to build your great ideas and work with you to further science. We also have an incredibly talented team of designers, developers, educators and researchers who want to make your idea into an awesome new Zooniverse project.
If you want to know more about this, you can get in touch with any of the team or via our general email address or on Twitter @the_zooniverse. We’re currently working on projects that were proposed earlier this year and we’ll be announcing them soon. Maybe yours will be next?
Gravitational lenses – or ‘space warps’ – are created when massive galaxies cause light to bend around them such that they act rather like giant lenses in space. By looking through data that has never been seen by human eyes, our new Space Warps project is asking citizen scientists to help discover some of these incredibly rare objects. We need your help to spot these chance-alignments of galaxies in a huge survey of the night sky. To take part visit www.spacewarps.org.
Gravitational lenses help us to answer all kinds of questions about galaxies, including how many very low mass stars such as brown dwarfs – which aren’t bright enough to detect directly in many observations – are lurking in distant galaxies. The Zooniverse has always been about connecting people with the biggest questions and now, with Space Warps, we’re taking our first trip to the early Universe. We’re excited to let people be the first to see some of the rarest astronomical objects of all!
The Space Warps project is a lens discovery engine. Joining the search is easy: when you visit the website you are given examples of what space warps look like and are shown how to mark potential candidates on each image. The first set of images to be inspected in this project is from the CFHT (Canada-France-Hawaii Telescope) legacy survey.
Computer algorithms have already scanned the images, but there are likely to be many more space warps that the algorithms have missed. We think that only with human help will we find them all. Realistic simulated lenses are dropped into some images to help you learn how to spot them, and reassure you that you’re on the right track. Previous studies have shown that the human brain is better at identifying complex lenses than computers are, and we know at the Zooniverse that members of the public can be at least as good at spotting astronomical objects as experts! We’re going to use the data from citizen scientists to continuously train computers to become better space warp spotters.
This is a really exciting project and you can read more on the Space Warps blog. As with our other projects it can also be found on Twitter (@SpaceWarps), on Facebook and you can discuss any interesting objects you find on Space Warps Talk. We’re really excited about this project and think you’ll be able to make some amazing discoveries through it.
It’s always a good feeling a be making a codebase open and today it’s time to push the latest version of Galaxy Zoo into the open. As I talked about in my blog post a couple of months ago, making open source code the default for Zooniverse is good for everyone involved with the project.
One significant benefit of making code open is that from here on out it’s going to be much easier to have Zooniverse projects translated into your favourite language. When we build a new project we typically extract the content into something called a localisation file (or localization if you prefer your en_US) which is basically just a plain text file that our application uses. You can view that file for our (US) English translation file here and it looks a little like this:
So how do I translate Galaxy Zoo?
I’m glad you asked… It turns out there’s a feature built into the code-hosting platform we’re using (called GitHub) which allows you to basically make your own copy of the Galaxy Zoo codebase. It’s called ‘forking’ and you can read much more about it here but all you need to do to contribute is fork the Galaxy Zoo code repository, add in your new translation file and (there’s a handy script that will generate a template file based on the English version), translate the English values into the new language and send the changes back up to GitHub.
Once you’re happy with the new translation and you’d like us to try it out you can send us a ‘pull request’ (details here). If everything looks good then we can review the changes and pull the new translation into the main Galaxy Zoo codebase. You can see an example of a pull request from Robert Simpson that’s been merged in here.
So what next?
This method of translating projects is pretty new for us and so we’re still finding our way a little here. As a bunch of developers it feels great to be using the awesome collaborative toolset that the GitHub platform offers to open up code and translations to you all.
One of the joys of working in the Zooniverse is the sheer variety of people who are interested in our work, and I spent a happy couple of days toward the end of last year at a symposium about Discovery Infomatics – alongside a bunch of AI researchers and their friends who are trying to automate the process of doing science. I don’t think they’d mind me saying that we’re a long, long way from achieving that, but it was a good chance to muse on some of the connections between the work done by volunteers here and by our colleagues who think about machine learning.
I’m still convinced that that will especially be needed as the size of datasets produced by scientific surveys continues to increase at a frightening pace. The essential idea is that only the proportion of the data which really needs human attention need be passed to human classifiers; an idea that starts off as a non-brainer (wouldn’t it be nice if we could decide in advance which proportion of Galaxy Zoo systems are too faint or fuzzy for sensible decisions to be made?) and then becomes interestingly complex.
This is particularly true when you start thinking of volunteers not as a crowd, but as a set of individuals. We know from looking at the data from past projects that people’s talents are varied – the people who are good at identifying spiral arms, for example, may not be the same people who can spot the faintest signs of a merger. So if we want to be most efficient, what we should be aiming for is passing each and every person the image that they’d be best at classifying.
That in turn is easy to say, but difficult to deliver in practice. Since the days of the original Galaxy Zoo we’ve tended to shun anything that resembles a test before a volunteer is allowed to get going, and in any case a test which thoroughly examined someone’s ability in every aspect of the task (how do they do on bright galaxies? on faint ones? on distant spirals? on nearby ellipticals? on blue galaxies? what about mergers?) wouldn’t be much fun.
One solution is to use the information we already have; after all, every time someone provides a classification we learn something not only about the thing they’re classifying but also about them. This isn’t a new idea – in astronomy, I think it’s essentially the same as the personal equation used by stellar observers to combine results from different people – but things have got more sophisticated recently.
As I’ve mentioned before, a team from the robotics group in the department of engineering here in Oxford took a look at the classifications supplied by volunteers in the Galaxy Zoo: Supernova project and showed that by classifying the classifiers we could make better classifications. During the Discovery Infomatics conference I had a quick conversation with Tamsyn Waterhouse, a researcher from Google interested in similar problems, and I was able to share results from Galaxy Zoo 2 with her*.
We didn’t get time for a long chat, but I was delighted to hear that work on Galaxy Zoo had made it into a paper Tamsyn presented at a different conference. (You can read her paper here, or in Google’s open access repository here.) Her work, which is much wider than our project, develops a method which considers the value of each classification based (roughly) on the amount of information it provides, and then tries to seek the shortest route to a decision. And it works – she’s able to show that by applying these principles we would have been done with Galaxy Zoo 2 faster than we were – in other words, we wasted some people’s time by not being as efficient as we could be.
A reminder of what Galaxy Zoo 2 looked like!
That doesn’t sound good – not wasting people’s time is one of the fundamental promises we make here at the Zooniverse (it’s why we spend a lot of time selecting projects that genuinely need human classifications). Zoo 2 was a long time in the past, but knowing what we know now should we be implementing a suitable algorithm for all projects from here on in?
Probably not. There are some fun technical problems to solve before we could do that anyway, but even if we could, I don’t think we should. The current state of the art of such work misses, I think, a couple of important factors which distinguish citizen science projects from other examples considered in Tamsyn’s paper particularly. To state the obvious: volunteer classifiers are different from machines. They get bored. They get inspired. And they make a conscious or an unconscious decision to stay for another classification or to go back to the rest of the internet.
The interest a volunteer will have in a project will change as they move (or are moved by the software) from image to image and from task to task, and in a complicated way. Imagine getting a galaxy that’s difficult to classify; on a good day you might be inspired by the challenge and motivated to keep going, on a bad one you might just be annoyed and more likely to leave. We all learn as we go, too, and so our responses to particular images change over time. The challenge is to incorporate these factors into whatever algorithm we’re applying so that we can maximise not only efficiency, but interest. We might want to show the bright, beautiful galaxies to everyone, for example. Or start simple with easy examples and then expand the range of galaxies that are seen to make the task more difficult. Or allow people a choice about what they see next. Or a million different things.
Whatever we do, I’m convinced we will need to do something; datasets are getting larger and we’re already encountering projects where the idea of getting through all the data in our present form is a distant dream. Over the next few years, we’ll be developing the Zooniverse infrastructure to make this sort of experimentation easier, looking at theory with the help of researchers like Tamsyn to see what happens when you make the algorithms more complicated, and talking to our volunteers to find out what they want from these more complicated projects – all in our twin causes of doing as much science as possible, while providing a little inspiration along the way.
* – Just to be clear, in both cases all these researchers got was a table of classifications without any way of identifying individual volunteers except by a number.
We were delighted by the response to our call for volunteers to attend our project workshop and we’re delighted to announce that our two winners are Katy Maloney and Janet Bain. Katy is a Planet Hunter from Montreal (you can see her in this recent video about online communities. Janet is well known to those from Old Weather where she serves as moderator of the very active forum.
As Jules explained in her post, these workshops are a chance for the strange mix of people behind the scenes of the Zooniverse – developers, educators and scientists – to get together to discuss what works and what doesn’t, and to plan the year ahead. We think it’s very important to have volunteers there – and we hope that Katy and Janet (along with Jules, who we’ve invited back) will keep you all informed and involved in the discussions.
There were a few comments in the discussion under that last post from people – particularly locals – who would clearly have dearly loved to come. Unfortunately, it wouldn’t be possible to run the workshop as a public event; both because of the format (which features spontaneously arranged small group discussions) and also to allow everyone to speak freely about often quite difficult issues. What I do find heartening is that we’ve grown a community who want to help us plan and develop for the future, and we need to take that seriously.
I’ll write more over the next couple of weeks and months about what we’re going to do to be more open, but for now for those who really wanted to come we’ll work hard to organise some truly public events. We have a meeting in Oxford on the 22nd June which I hope British Zooites will be able to attend, and we’ll arrange a similar event in Chicago as soon as possible. We’ll also try hard to webcast these events so all can attend.
Since this post was written, SciStarter have changed their policies and now provide direct links to projects. This is a good thing, and I’m happy to acknowledge it here.
Chris – April 2017
Preface: I’d like to begin by saying that I’ve met Darlene Cavalier at conferences in the past and I’m a big supporter of her efforts. Darlene is truly is a ‘cheerleader’ for citizen science, her enthusiasm is infectious and the citizen science domain is clearly a better place with her. I’m writing here about what I consider the bad practice of SciStarter.com and Science For Citizens LLC, their parent organisation. I have no idea whether the issues highlighted here are because of decisions that she has made.
There was a time not so long ago when you needed a new account for pretty much everything you tried out on the web. Want to upload photos to Flickr? Then signup for a Yahoo! ID. Want a blog? Then give WordPress or Tumblr your details. Feeling social? Then FaceBook, Twitter or MySpace would pretty much want the same information. These days there are a number of solutions that allow you to log in to web-based services using things like your Facebook, Twitter or Google account. Under the hood these solutions typically rely on a couple of protocols such as OAuth and OpenID and often still request your email address when you sign in but the days of hundreds of accounts each with their own password to remember are coming to a close.
In many ways a request by an organision for your email address when signing up for a new service is completely reasonable. In exchange for handing over your email address and a few personal details these tools were often available for free – both parties win. There is of course the discussion around who or what is the product when you use these free services but let’s not go into that here.
Since launching the original Galaxy Zoo back in 2007 we’ve encouraged our volunteer community to register for an account with us, although for the vast majority of our projects (and all of our recent ones) this login/signup is an optional step. For the Zooniverse there are two main reasons for asking you to create an account:
1) When we publish a paper as a result of your efforts we feel extremely strongly about crediting you for your efforts. Experience has taught us that attempting to publish a paper with 170,000 authors on is somewhat frowned upon by the journals but if you take a look at any of the Zooniverse publications you’ll find a link to an authors page such as here, here and here. We can only credit you if you share some personal information with us when you sign up.
2) For our research methods to work well, identifying an individual ‘classifier’ is pretty important. You can read more about this here (the original Galaxy Zoo paper) or here but in order to produce the best results possible we spend lots of time working out who is ‘best’ at a particular task and weighting their contributions accordingly. Being able to reliably identify an individual throughout the lifetime of a project (and even between projects) is most simple when someone has logged in.
Over the past year or so I’ve become increasingly concerned by the behaviour of SciStarter.com – a website that indexes citizen science projects from across the web. The site does a pretty good job of cataloging citizen science projects you can contribute to – when you visit the site and search for example for ‘bats’ the Zooniverse project Bat Detective is listed in the results. Selecting the result takes you to a brief summary of Bat Detective and offers you a link to ‘get started now!’ and this is where it goes wrong: Rather than taking you straight to the Bat Detective site you have to be ‘logged in’. Sign up for what exactly? Am I signing up to take part in Bat Detective? No. You’re actually just signing up for an account with SciStarter.com just so you can get a link to a project that SciStarter.com has nothing to do with.
Additionally, in a recent ‘top 10’ blog post of most successful citizen science projects of 2012, Bat Detective was highlighted. Did the link in this article send you straight to the Bat Detective website? Sadly not, it of course links to SciStarter’s catalogue page about Bat Detective which requires account registration before you can access the URL.
To me this doesn’t seem right and in many ways this is just exploiting people’s lack of experience and understanding of the web. There’s a reason that Facebook.com is in the consistently the most Googled terms – many people just don’t quite understand how the web works and I think SciStarter.com are exploiting this. Conversly, for those who are a little more web savvy these tactics must seem very clumsy. Perhaps more importantly though, it’s widely recognised that signup forms are a barrier to entry for many people and so by having people jump through this hoop SciStarter.com are actually holding potential citizen scientists back.
I don’t believe it’s in anyone’s interest other than Scistarter’s to require you to sign up to follow a link through to a project. By mandating this step they are building an index of individuals interested in other people’s projects when they don’t have any of their own and they’re risking confusing new community volunteers about what they have and haven’t signed up for. All of this is made worse by the fact that SciStarter.com is a division of Science for Citizens LLC – a commercial company.
So my challenge to SciStarter.com is this: If you’re so committed to citizen science then why put up this artificial barrier to contribution? Crawling the internet for people’s emails is one of the less tasteful aspects of the web and one I’d hoped we’d seen the end of. So how about it SciStarter?
It’s almost a year since I attended the first ever Zooniverse Project Workshop in my role as an advisory board member. In April the second Zooniverse workshop will convene to discuss yet more exciting new projects. I’ll be there and hopefully so will Alice Sheppard (if her exam timetable permits!) This year, however, there is funding available for one more volunteer to attend. This is a responsible role for a dedicated and enthusiastic Zooite and that could be you!
This is a fantastic opportunity to meet the science teams behind projects old and new and to find out just what is involved in getting a project up and running. You will attend some great presentations and have the chance to contribute to some fascinating discussions and workshops. Last year we covered things such as design, how to get the best science out of a project and how to create the best user experience. You need to be prepared to take part in discussions and to talk about your experiences as a Zooniverse volunteer. The more you put in the more rewarding the conference will be and you’ll find that your contribution will be hugely respected and valued. Volunteers can make or break a project and I was certainly made to feel that my input was extremely important.
There is only one place available, however, so to help the team decide who gets to go please tell us in no more than 250 words a little about yourself, why you think you should go and what you can contribute to the discussions as a volunteer. Please add your full name and preferred e-mail address and send this to team@zooniverse.org with the subject line CHICAGO PLEASE. The closing date is 12 noon GMT on Thursday 7 March 2013. The Zooniverse team will choose the successful entry.
The conference will be held over two days at the Adler Planetarium, Chicago on 29 and 30 April 2013. Flight and hotel expenses will be reimbursed in full.
This really is a fantastic opportunity to contribute to citizen science and the future of the Zooniverse – don’t miss out!
For a detailed account of last years event have a look at the notes on my blog.
Taking the Zooniverse open source is something we’ve been thinking about for a long time. As the field of citizen science expands into ever broader domains the number of tools available to people to start their own projects is still low. Since the launch of Galaxy Zoo 2 we’ve been building tools that allow for code reuse across a number of projects and while the majority(1) of our software has never been ‘officially’ open, behind the scenes we’ve been sharing with pretty much anyone who asked, often talking them through the thought process that led us to design our software in a particular way.
Because of our natural inclination to share with those who approached us, we’ve never really made publishing our code a priority. As with most closed source projects there are also a number of pretty boring (but sometimes important) reasons for not publishing – we worried about how usable the code we’d written was to people we didn’t work closely with – as a small team we favour clean code and conversation with other developers over heavy documentation. Some sensitive information around our production environment inevitably slipped into the codebases which mean’t lots of work to clean up and security audit our tools. Some of these reasons hold for legacy applications each project we start often comes with a new Git repo and an opportunity to develop in a different way.
It’s important to say here that we’re not expecting a community of developers to jump in a help us develop new projects (although that would be pretty cool), but if there’s a typo on our site or a really annoying bug that you know exactly how to fix then fork the repo and send us a pull request and we’ll see what we can do. Significantly for our localisation support (translating sites into multiple languages) we’re proposing that new translations should be submitted in exactly this way (2). There are a huge number of very talented people in the Zooniverse community who until today had no way of contributing to the project other than to help analyse data. That changes today.
We’re releasing our software under a very liberal license – Apache 2.0. In very simple terms this means that the tools we develop can be used for whatever you like provided you follow the rules of the Apache 2.0 license.
What aren’t we open sourcing?
In truth lots of legacy code for our older projects aren’t likely to make it into the open. A large number of our projects between 2009 (Galaxy Zoo 2) and 2011 (The Milky Way Project) were all built upon a shared codebase called The Juggernaut. While we’re not making each of the projects open we’re are publishing the common application core which has been kept up to date and runs on Rails 3.1.
We’re also not opening up our applications that hold sensitive user information and are mission-critical for the operation of the Zooniverse. That’s not to say we won’t ever do this, we’re just not comfortable publishing these applications at this point. This basically means that the application that powers Zooniverse Home (www.zooniverse.org) and an application called Ouroboros (api.zooniverse.org) that serves up images and collects back classifications aren’t part of our open source strategy.
Why now?
Aside from the reasons mentioned above, there are a number of reasons to make open source our default position. In part it’s about people – developers these days are often hired (or at least shortlisted) by their GitHub profiles that show which projects they’ve been working on. As our team grows and we hire talented young developers we’re doing them a disservice not allowing them to show off the awesome work they do. It’s also about the way in which we as the Zooniverse do science. We believe citizen science is an inherently open way of doing research, we often work with open datasets (such as SDSS) and ask people to donate their time and efforts to a project that in the end produces open data products for the research community to enjoy (e.g. data.galaxyzoo.org, data.milkywayproject.org). Having a closed codebase for everything we do just feels incompatible with this way of doing research.
What’s next?
To be honest we’re not quite sure. Going forward, our projects will typically become open source as we launch them. If there’s a Zooniverse project that you think you’d like to rework for a different purpose then there’s now nothing stopping you from doing this. If you’re interested in helping us with a new translation for your favourite project then we’d love to talk. Perhaps you’re just interested to see how some of our applications work. Regardless, we invite you to take a look and give us feedback. The Zooniverse has always been about harnessing the crowd to make science happen. From today, there is a new way for people to contribute to that goal.
Cheers
Arfon
Footnotes: 1. Scribe, our open source text transcription framework grew out of Old Weather and has been used on a number of projects now. 2. A fuller article about language support is coming very soon on this blog.
The world's largest and most popular platform for people-powered research. This research is made possible by volunteers—millions of people around the world who come together to assist professional researchers.






 Zooniverse
